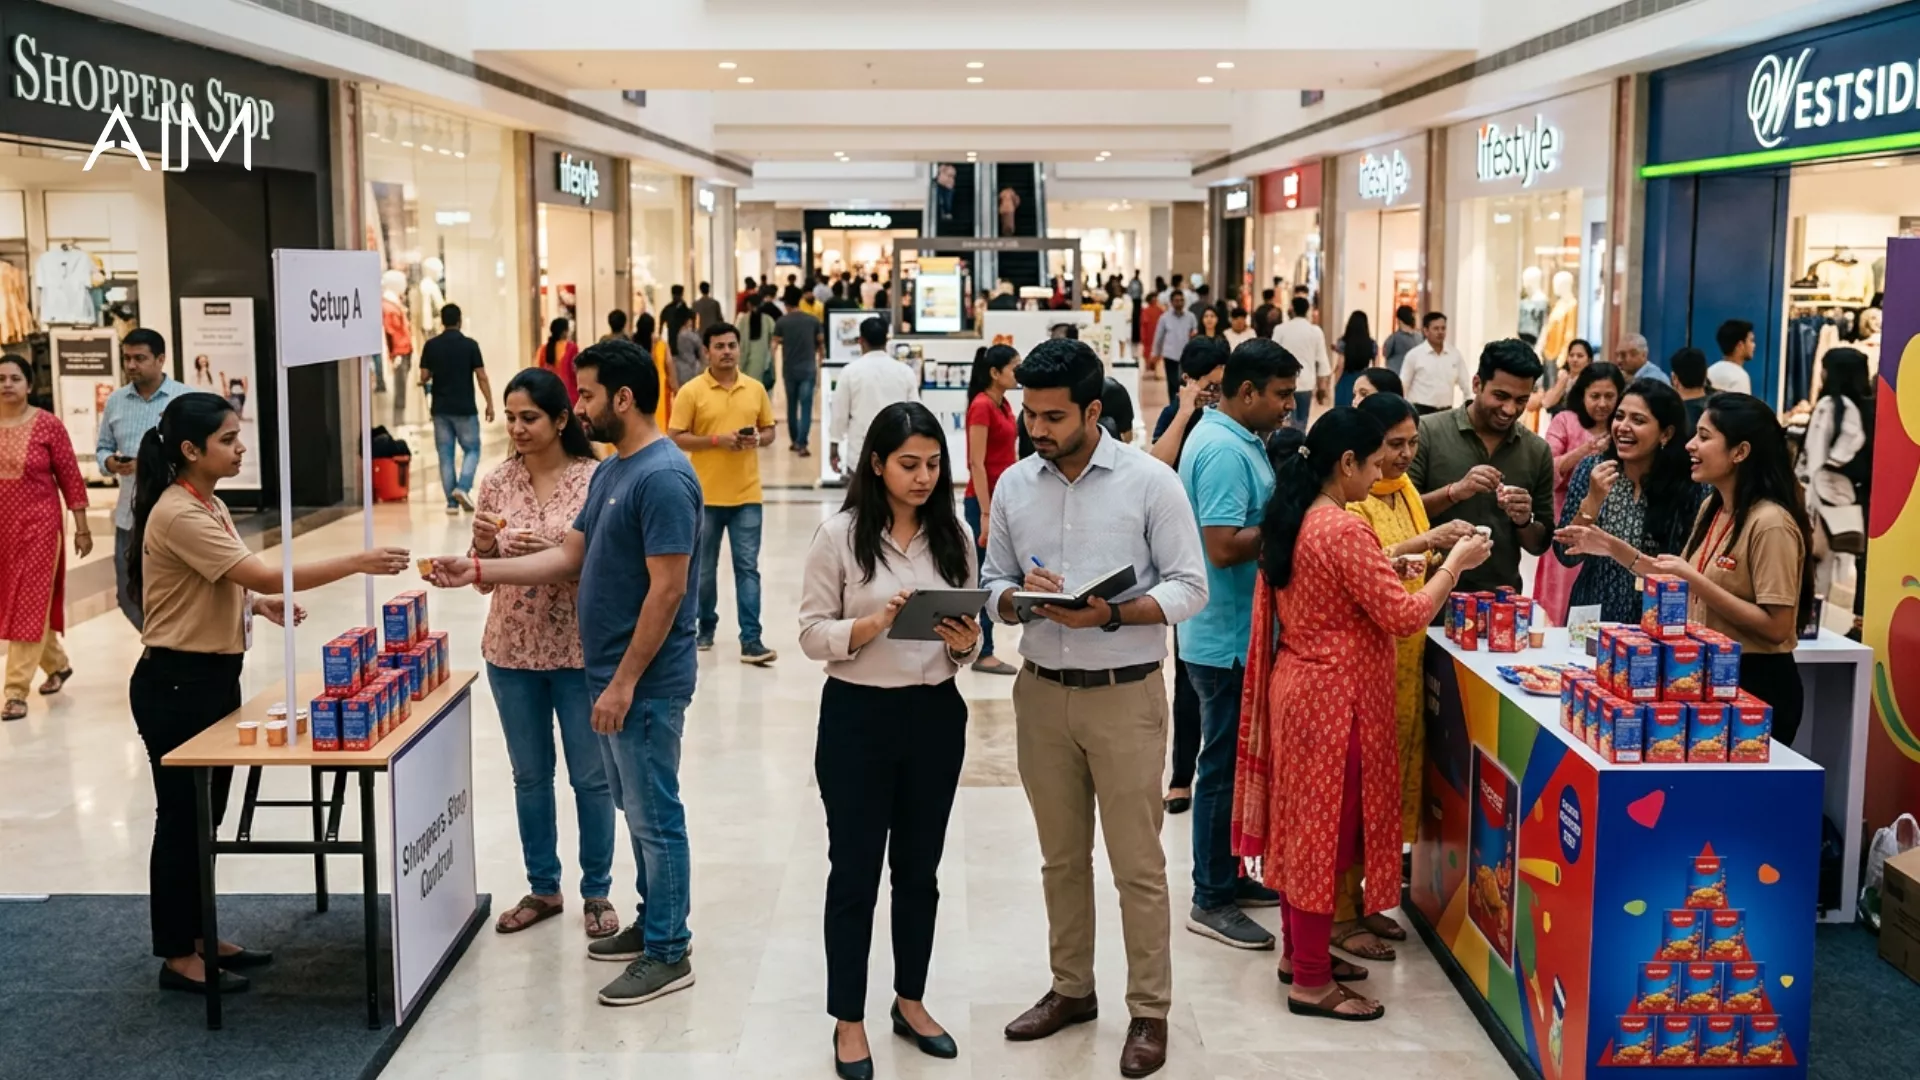


Most brands run a sampling campaign, judge it as a success or a failure, and move on. What they rarely do is design the campaign so that it teaches them something precise about what to do differently next time. That is what A/B testing is for. Instead of running one version and hoping, you run two deliberately different versions side by side, keep everything else the same, and let the difference in results tell you which choice actually worked and why. Done well, it turns every campaign into an experiment that makes the next one sharper, rather than a one-off bet you can only grade after the fact. Over time, a brand that tests learns the real rules of its own category, while a brand that only guesses keeps repeating the same expensive assumptions.
A/B testing in sampling is not complicated, but it is disciplined. The whole value depends on two rules: changing one thing at a time, and measuring the right outcome. Here is how to do it properly.
What is A/B testing in product sampling?
A/B testing means running two versions of your campaign at the same time, identical in every way except one deliberate difference, and comparing how each performs. One group gets version A, a comparable group gets version B, and because everything else is held constant, any gap in results can be attributed to the single thing you changed. It is the difference between guessing that a bigger sample converts better and actually proving it by giving one matched group the bigger sample and the other the smaller one. One is an opinion; the other is a finding you can build on.
The reason this matters is that sampling has too many variables to improve by intuition alone. Sample size, location, timing, the offer attached, the audience, the staff, the messaging, all of them affect the result, and a single campaign tangles them together so you can never tell which one drove the outcome. A/B testing isolates one variable so you actually learn something. It trades a little extra planning for the ability to say, with confidence, this specific choice is what made the difference, which is worth far more than a vague sense that the campaign went well.
What should you test first?
Start with the variable most likely to move the result, because an early clear win builds the case for testing everything else and gets the whole team comfortable with the method. In sampling, a few variables usually matter most and are worth testing before the smaller ones.
Test the offer attached to the trial, because the bridge from liking to buying is where most conversion is won or lost. Version A gets one incentive, version B gets another, and you learn which actually drives purchases rather than assuming. Test the sample size, because too small a trial fails to convince and too large a one wastes product, and the right size is rarely a guess worth trusting. Test the location or channel, because where a trial happens often matters more than anything about the trial itself. And test the audience, because reaching a slightly different profile can change the conversion rate dramatically while costing the same to run. The same product, the same sample, the same offer, placed in front of a better-matched audience, can produce a completely different result, and only a clean test will show you by how much.
What you should not do is test everything at once. The appeal of changing several things together to save time is exactly what destroys the learning, because when two versions differ in three ways, a difference in results tells you nothing about which of the three caused it. One variable per test is the rule that makes every other part of the method work. You will have run a more expensive campaign and still be guessing, which defeats the entire purpose of testing in the first place.
How do you set up a valid sampling A/B test?
A few conditions have to hold for the test to mean anything. The two groups must be genuinely comparable, similar in audience, location type and timing, so that the only real difference between them is the variable you are testing. Testing a bigger sample in a premium neighbourhood against a smaller one in a budget one proves nothing, because the neighbourhoods differ as much as the samples. Any result you get is hopelessly confounded, and you will not know whether the sample size or the neighbourhood produced the gap you are looking at.
Only one variable can change between A and B. The moment you change two, the test is broken, because you can no longer attribute the result. If you want to test three things, you run three clean tests, not one messy one.
The groups must be large enough for the result to be real rather than noise. A handful of people in each version can swing on luck alone, and a difference you see might vanish if you ran it again. The test needs enough people that a clear gap is believable, not an accident of small numbers.
And you have to decide the success metric before you start, not after. Choose the outcome that matters, usually conversions or cost per acquired buyer, and commit to judging both versions on that same number. Picking the metric after you see the results is how brands fool themselves into declaring whichever version they preferred the winner. Committing to the number in advance keeps the test honest and the conclusion worth acting on.
What should you measure to pick the winner?
Measure the outcome that reflects real business value, not the one that is easiest to count. Samples handed out tells you nothing about which version worked. The honest measures are how many people in each version converted to a purchase, and what each acquired buyer cost. A version that handed out fewer samples but produced more buyers at a lower cost per buyer is the winner, even if it looks less impressive on volume, and choosing it over the flashier version is exactly the kind of decision testing exists to make. Judging an A/B test on trial numbers rather than conversions is one of the most common ways brands learn the wrong lesson from a good experiment.
It also helps to watch the fuller journey where you can: not only the first purchase but the repeat, because a version that wins on first purchase but loses on repeat may not actually be the better choice. The deeper you can see, the more trustworthy the conclusion. A quick read on first purchase is useful, but the version that builds more lasting customers is the one genuinely worth scaling.
How do you turn the result into a better next campaign?
The point of the test is not the test. It is the decision it hands you for next time. Once a version wins clearly, that choice becomes your new default, and the next campaign builds on it rather than re-litigating it, and that settled question never has to be asked again. Then you test the next variable from that improved baseline. Over several campaigns, this compounds: each one is a little sharper than the last, because each one settled a question the previous one left open. A brand that tests one variable per campaign and keeps the winners is, within a few campaigns, running sampling that is measurably better than where it started, with the evidence to prove why. That evidence matters beyond the campaign itself, because it lets the team defend its choices and its budget with proof rather than opinion, which changes how sampling is treated inside the business.
The discipline is to resist the urge to overhaul everything between campaigns, which throws away the ability to learn, and instead change one thing, measure it cleanly, keep what won, and move to the next question. Patience is the whole method. The brand that changes one variable per campaign will overtake the brand that reinvents its approach every time, because only one of them is actually accumulating knowledge.
How we do A/B testing in product sampling
At AIM, sampling campaigns are built to produce learning, not only trials. Where the scale allows, two comparable groups are run with a single deliberate difference, whether that is the offer, the sample size, the location or the audience, with everything else held constant and the success metric, usually conversions and cost per acquired buyer, fixed before the campaign starts. The winning choice becomes the baseline for the next campaign, and the next variable is tested from there, so the program gets sharper over time rather than repeating the same guesses year after year. The aim is simple: every campaign should leave the brand knowing something true about what works that it did not know before, so the next one performs better on evidence rather than hope.